A chatbot answers. An agent acts.
Ask a chatbot "Where's my order?" and the best it can do is tell you how you might find out. An agent looks it up. The difference isn't a smarter model. It's three things wrapped around the same model. We call them CTL: Context, Tools, Loop.
C: Context
Context is everything the model sees on a given turn: the system prompt, the conversation so far, the descriptions of the tools it may use, and the results of any tools it already called. The model has no other memory (remember 0.3, How LLMs work), so context is the agent's entire world. Most "the agent is being dumb" problems are context problems: too little, too much, or the wrong stuff.
T: Tools
A tool is a function someone wrote, plus a description the model reads:
{
  "name": "lookup_order",
  "description": "Get status and shipping details for an order by its id.",
  "parameters": { "order_id": { "type": "string" } }
}
The model can't run the function. It can only reply with a request: "call lookup_order with order_id = 4721". The code around the model decides whether to run it, runs it, and hands back the result. That boundary is where permissions, validation and safety live, and it's why FDEs care so much about tool design.
L: Loop
One call isn't enough: the model needs to see the tool's result before it can answer. So you loop. In the book's words (Book §3.2):
- Read. The model gets the conversation plus attached context.
- Plan. It decides what to do next: call a tool, or answer.
- Act. The harness turns that into a real action.
- Observe. The result is appended to the conversation.
- Repeat until the model answers without asking for a tool, or you hit a step limit.
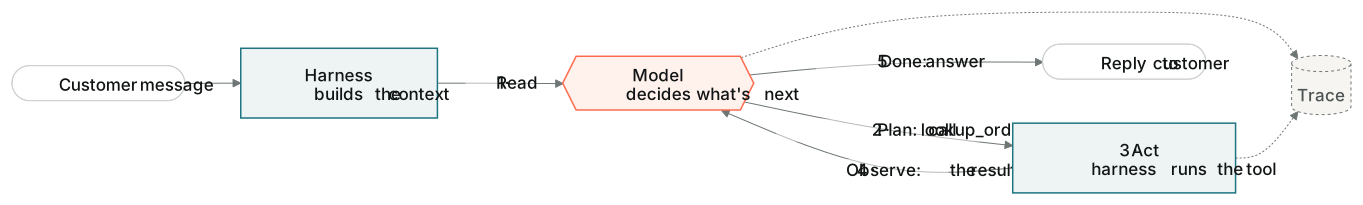
This pattern, reason then act then observe, is known as ReAct. Step through one real turn for Parcelly, a small delivery company, under this reading.
Reading a trace
A trace is the log of every step in that loop. When an agent misbehaves in production, the trace is the first thing you open: what did it see, what did it decide, what came back? Claude Code shows you its own loop as it works: every file it reads and every command it runs is a step, and you can ask it to explain any of them. In this topic's steps you give it a support ticket and then ask it to walk you back through what it did. In the bootcamp you'll be evaluating whole trajectories like that one.
Three things that follow
- Agents cost more than chatbots. Every loop iteration resends the whole conversation.
- Agents can get stuck. A bad plan leads to a confusing observation, which leads to a worse plan. Always cap the steps.
- The loop is yours to shape. Which tools exist, what's in context, when to stop, when to ask a human. That's the design space of Module 1, and in Module 2 you build that loop yourself.
In the next topic, you'll see that Claude Code is this exact loop with a very good set of tools, plus permissions and memory. That wrapper is called the harness.